Text Extractor EN
Nish kumar · EEdge MV3
Copy page text with Ctrl+click or right-click. Read image text locally in 100+ languages. Edit, clean, and export.
<all_urls>),意味着它可以读取你在任意站点的页面内容,包括已登录的页面。这是许多扩展正常工作的必要条件,但也值得你确认来源可信。
截图
简介
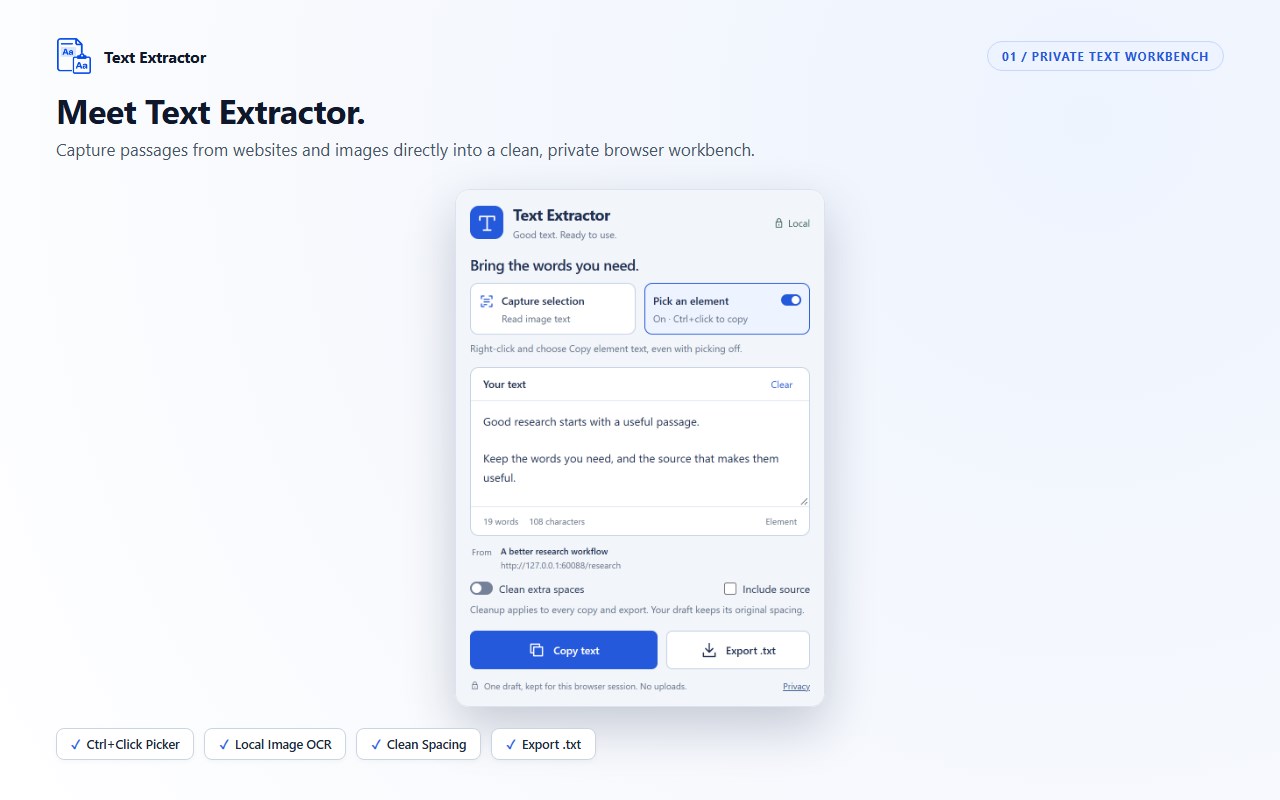
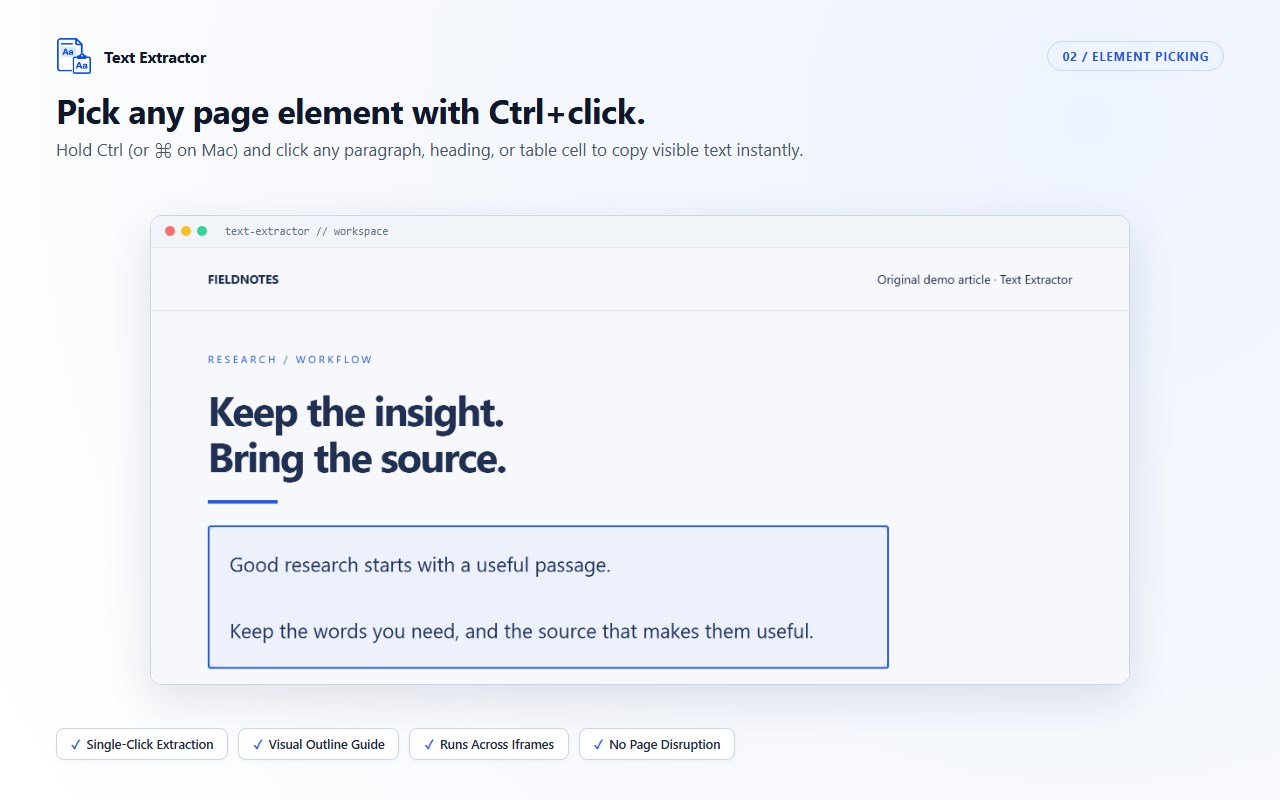
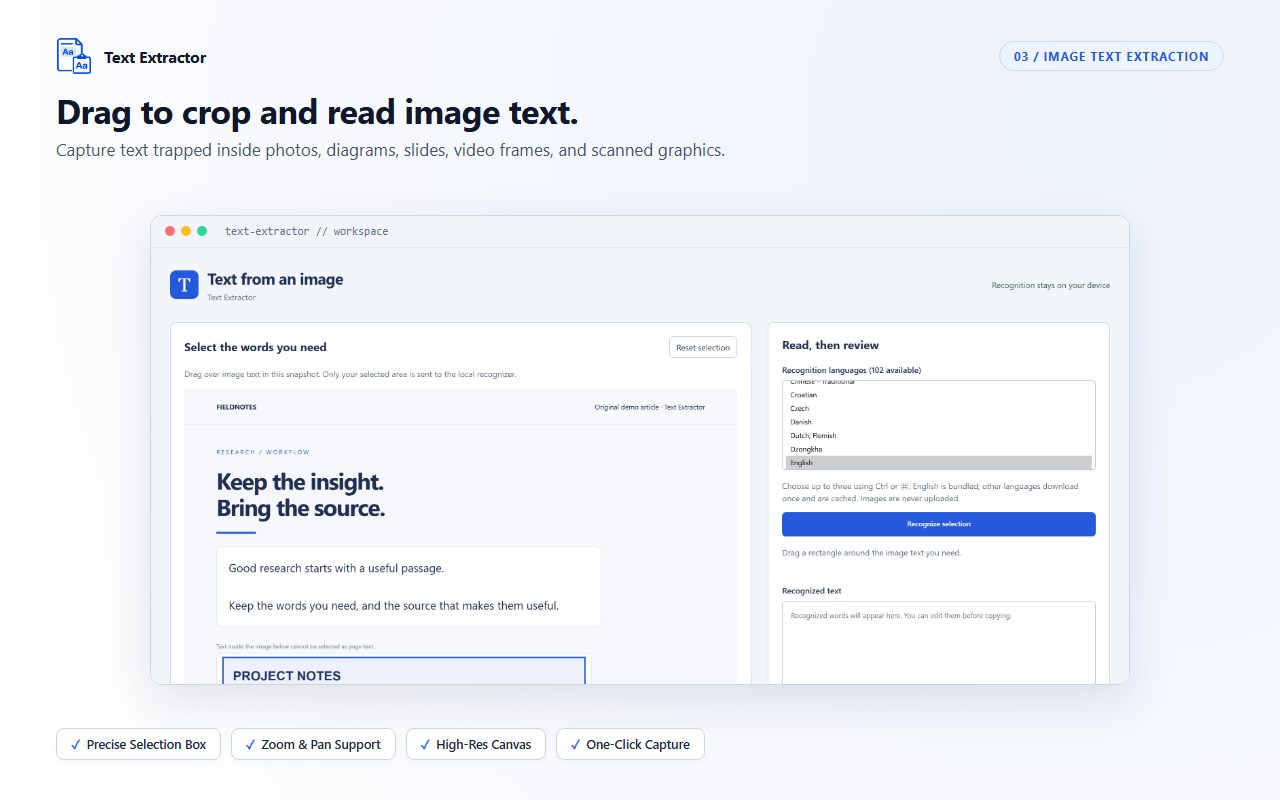
Text Extractor helps you capture text from websites and images quickly, then review, clean, copy, and export it in a simple local workflow. The extension is built around practical text extraction without relying on a remote recognition service for the captured content itself. It supports three main ways to collect text. You can activate an element picker and use Ctrl+click on a paragraph, heading, or section to grab its visible text. You can also right-click an element on a regular HTTP or HTTPS page and use the “Copy element text” command from the context menu. For text that appears inside images, screenshots, banners, scanned content, or graphics on a page, you can capture the visible page, open a separate workspace, draw a selection around the area you need, and run local OCR to recognize the words.
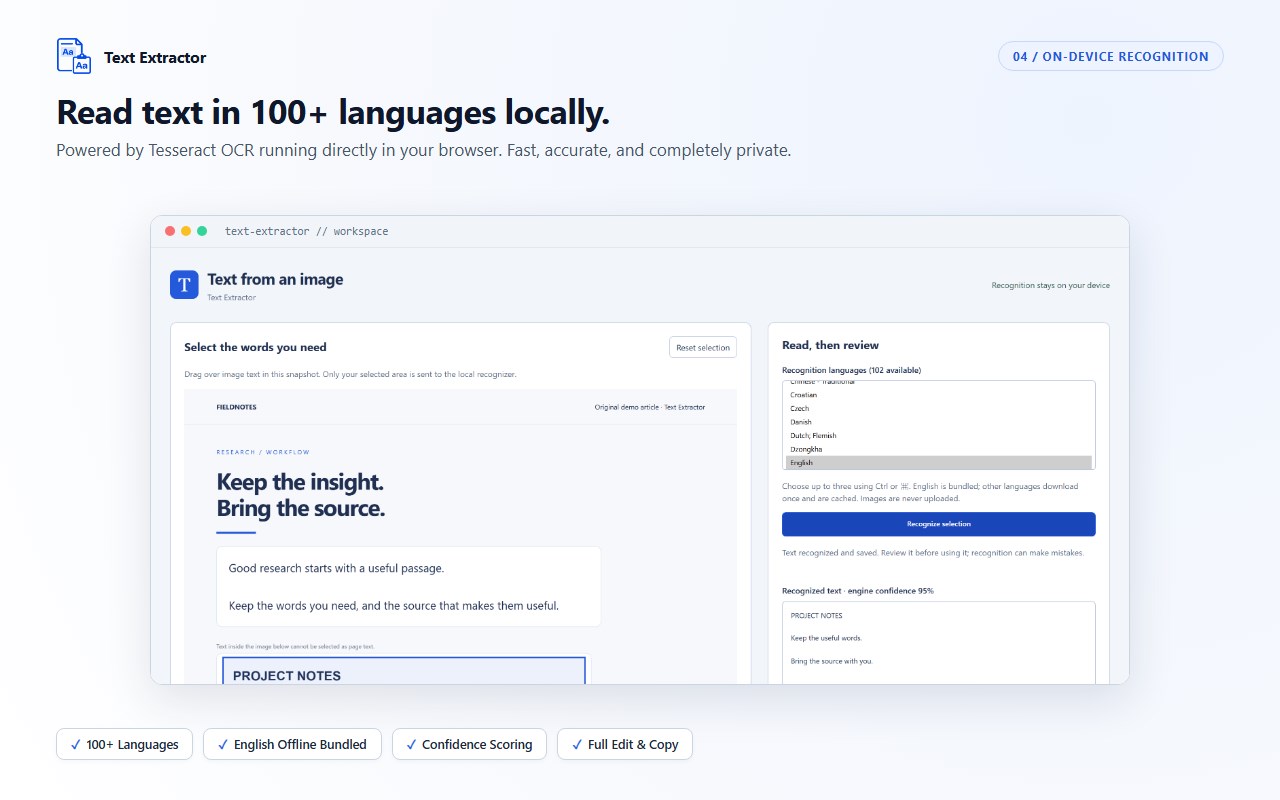
The extension is designed to stay focused and easy to use. Its popup presents the main actions clearly, including options for page text capture and image-based text extraction. When the picker is enabled, an on-page outline highlights the current target so you can see exactly what will be captured, while a small instruction bar explains that normal clicks still behave normally and that Ctrl+click performs the extraction. If a selected element does not contain visible text, the extension lets you know and prompts you to try a different paragraph, heading, or section. For image text, the OCR workspace keeps your task available in a separate area where you can drag a rectangle over the relevant words and generate a recognized result with a confidence value.
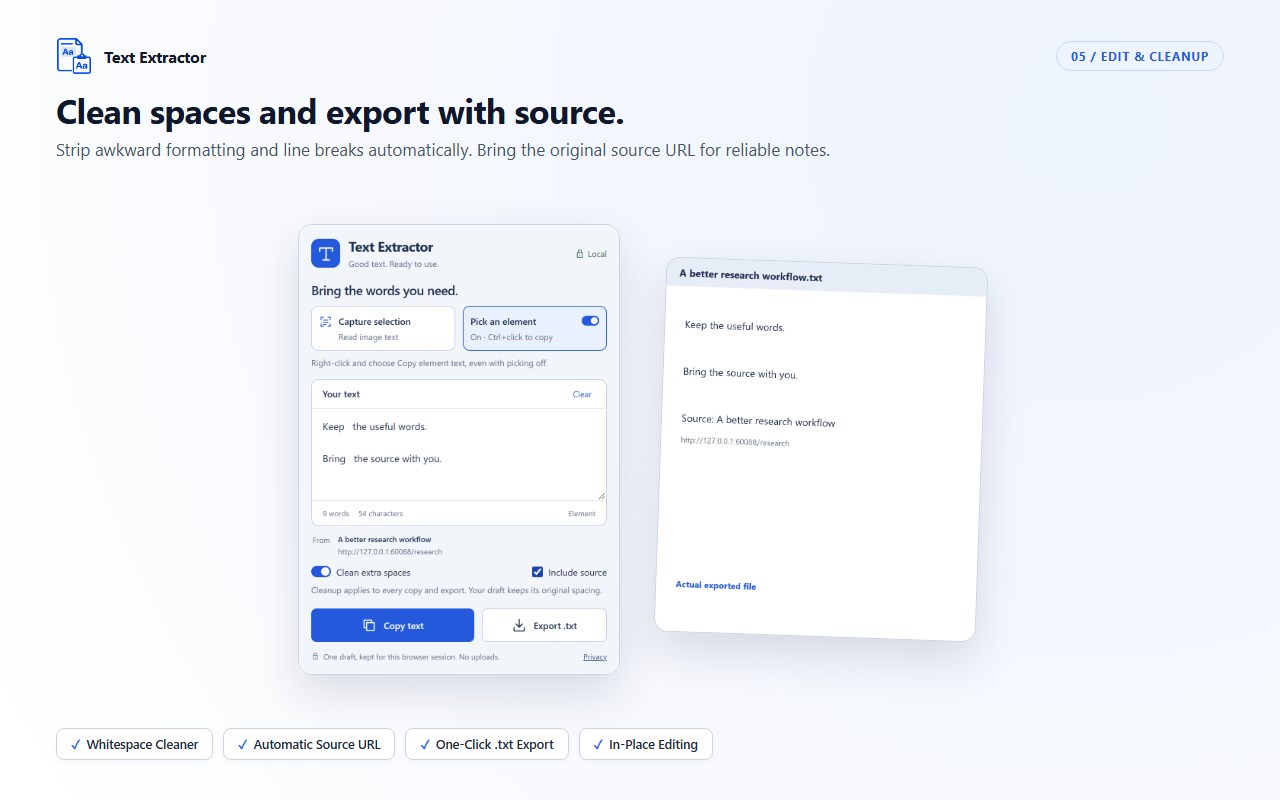
Text Extractor also works as a temporary draft space for the current browser session. After capture, the latest result is stored as a draft so you can review it, refine it, and reuse it without repeating the extraction step right away. You can clean extra spaces, optionally include the source page title and URL, copy the result directly to the clipboard, or export it as a plain .txt file. The package also indicates support for OCR language selection, with English bundled and additional language data available for download when chosen. User guidance and safeguards such as overlays, notifications, validation, and limits help make the workflow clear and reliable on supported pages.
Key Features:
- Capture text in multiple ways with Ctrl+click element picking, right-click context menu extraction, and screenshot-based OCR.
- Use local OCR in a dedicated workspace to recognize text from images on the visible page.
- Keep the latest extracted result as a session draft for quick review, reuse, and refinement.
- Clean extra spaces and optionally include the source page title and URL in copied or exported output.
- Copy extracted text directly to the clipboard or export it as a plain .txt file.
- Choose OCR languages with English bundled and additional language data available for download when selected.
- Benefit from built-in guidance such as visual overlays, prompts, validation, and safeguards for unsupported pages or invalid selections.
How It Works:
1. Open the extension on a regular HTTP or HTTPS website and choose whether you want to capture page text or image text.
2. For page text, enable “Pick an element” and Ctrl+click the target paragraph, heading, or section, or right-click an element and choose “Copy element text.”
3. For image text, select “Capture selection,” let the extension capture the visible page, and open the OCR workspace.
4. Drag a rectangle around the part of the image that contains the text you want to recognize.
5. Review the extracted result in the draft area or workspace, and adjust output options such as cleaning extra spaces or including the source.
6. Copy the text to your clipboard or export it as a plain text file for later use.
7. Capture new content at any time to replace the current session draft, or clear the draft when you are finished.
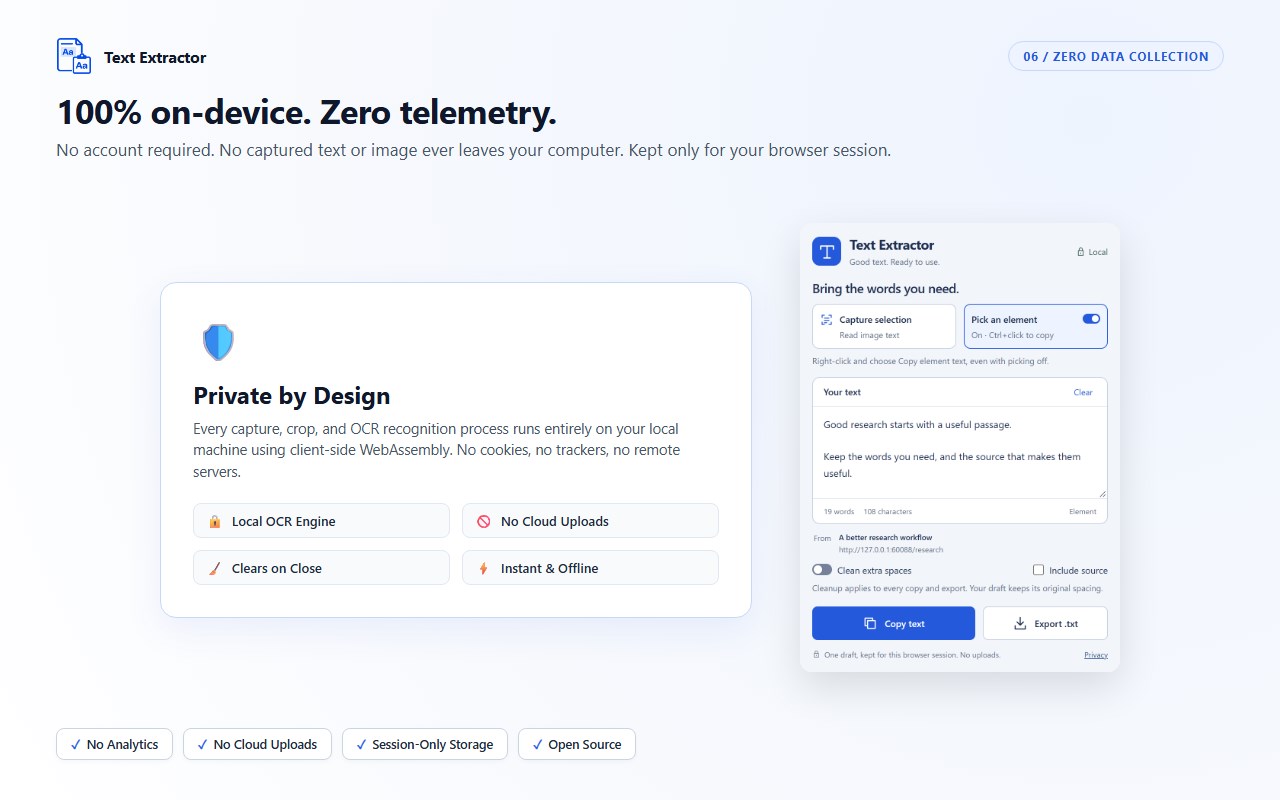
Privacy: - This extension is primarily local and does not upload captured text, screenshots, page titles, or source URLs. It stores only the latest draft in session storage and keeps preferences such as formatting options and selected OCR languages locally on the device. English OCR data is bundled. If you choose additional OCR languages, the extension downloads static language data from cdn.jsdelivr.net, which means the CDN receives ordinary connection data such as your IP address, but the request does not include the screenshot, recognized text, page title, or source URL.
Text Extractor 是做什么的
Text Extractor 是一款面向 Edge 的效率工具类扩展,主要用来管住注意力、屏蔽干扰站点、记录时间。官方对它的介绍是:Copy page text with Ctrl+click or right-click. Read image text locally in 100+ languages. Edit, clean, and export.在微软 Edge 加载项商店上,它当前版本 1.0.0,评分 5(1 人评价),约 3 名用户。
适合什么人用
从功能定位看,Text Extractor 更适合想专注工作学习、减少无效刷网页的用户。如果你平时只是偶尔遇到相关需求,用浏览器自带功能也能凑合;但如果这件事每天都发生,装一个专门处理它的扩展通常比手动操作省事得多。需要注意的是它作用于所有网站,装上后建议先观察一两天,确认不影响常用站点的正常使用。
怎么安装 Text Extractor
- 打开微软 Edge 加载项商店上的官方页面;
- 点「添加到浏览器」并确认权限提示;
- 装好后在扩展列表里固定图标,方便随时开关。
本站只做索引与介绍,安装包来自官方商店。如果商店页面提示当前地区不可用,说明该扩展未在你所在区域上架。
常见问题
Text Extractor 是免费的吗?
Text Extractor 在微软 Edge 加载项商店免费提供下载。它是浏览器扩展,装上就能直接用,不需要注册账号。
Text Extractor 安全吗?
它只申请了 0 项权限,范围比较克制,没有申请「读取所有网站数据」这种大权限。
Text Extractor 支持哪些浏览器?
当前收录的版本来自微软 Edge 加载项商店,适用于 Edge。同一个扩展在其他商店可能有对应版本,但功能与版本号不一定相同。
怎么卸载 Text Extractor?
在扩展管理页找到 Text Extractor,点移除即可。它在本地保存的设置会一起清掉,不会残留数据。
权限清单 来自 manifest.json 原文
站点访问(可选) 2
http://*/*https://*/*
接口权限 5
activeTabclipboardWritecontextMenusscriptingstorage
其他商店也有这款
同一款扩展在不同浏览器下的版本,权限与更新节奏可能不同